Youssef

I measure what AI does.

I build open tools that test whether AI does what it claims, and I publish every result, the bad ones too. AI product engineer, founder of mokka.

Connect on LinkedInSee all 47 projects

What I am working on

forecast-arena brand banner: AI forecasting models tested against two real German systems

lowest price-forecast error (MAE) of the eight.

Chronos-2 on the German day-ahead price, averaged over all 24 delivery hours. The simple seasonal baseline scores 28.20.

forecast-arena

Eight forecasting models tested on German train delays and day-ahead power prices. The losses are published next to the wins.

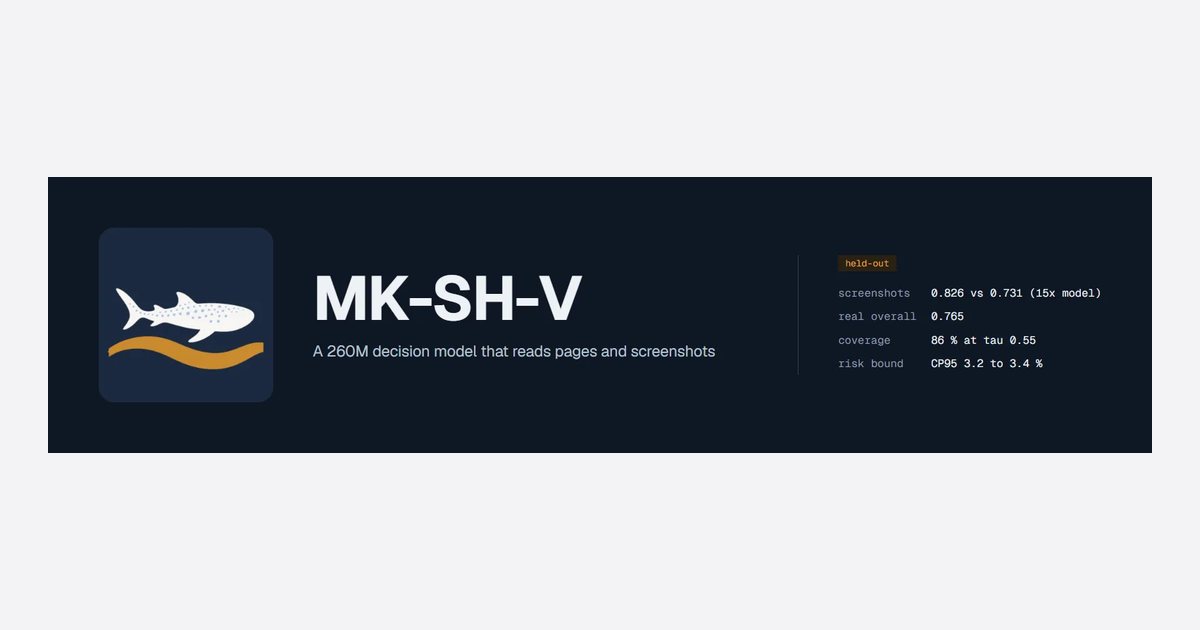
accuracy on held-out real screenshots; a model 15× larger scores 0.731 zero-shot.

The released checkpoint on the held-out real-screenshot test. The refusal gate was fitted on a separate calibration split, by a rule frozen in advance.

MK-SH-V

A 260M visual decision model I trained from scratch. It reads documents and screenshots, answers with calibrated odds, and refuses instead of guessing when its confidence sits below a validated gate.
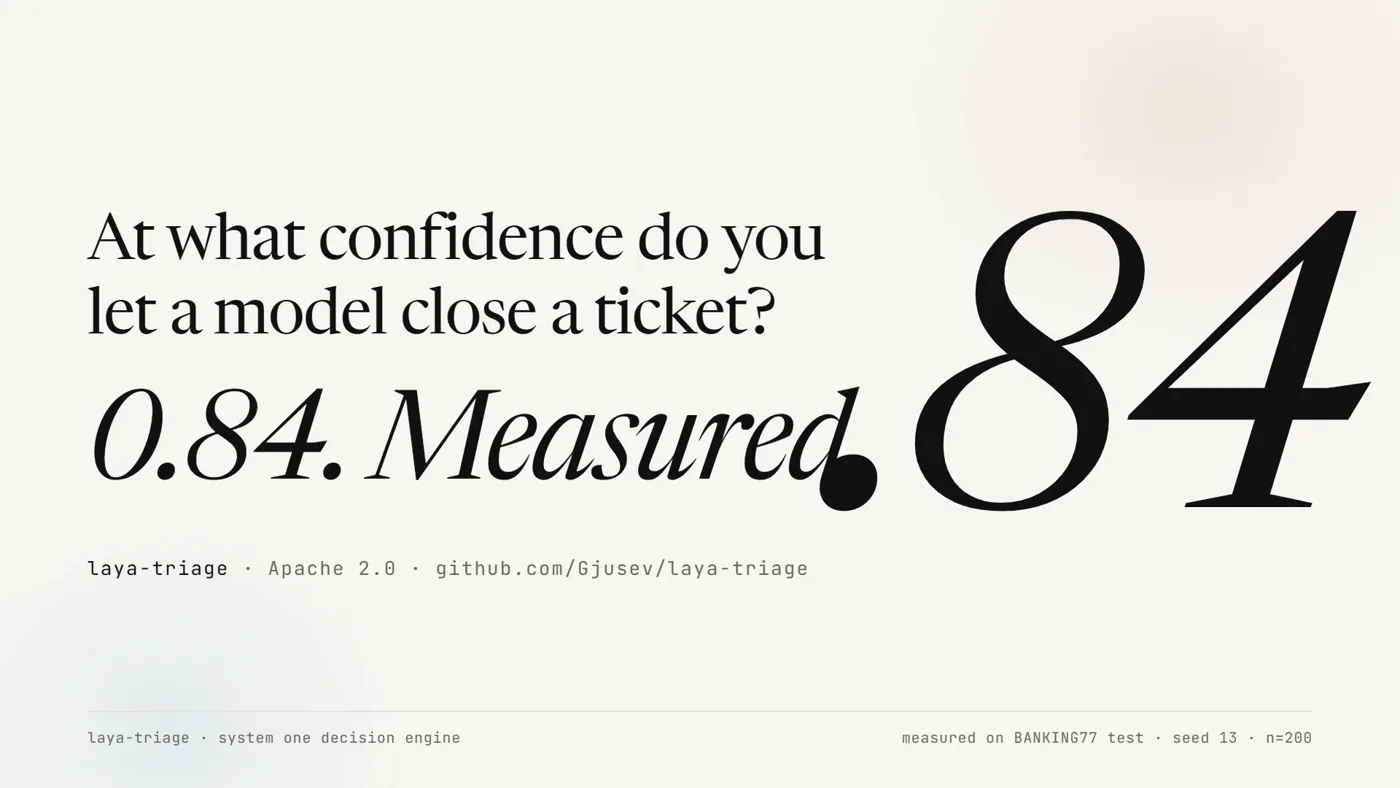
Poster reading

confidence the model needs before it closes a ticket.

Measured on the BANKING77 test set, seed 13, 200 tickets.

laya-triage

Routes support tickets in any language with a local model, and hands a ticket to a person when the model is not sure.

quality gates on every release.

Word error rate, response time, behaviour when interrupted, and whether the caller's task got done.

voice-evals

Tests a voice agent the way callers use it. It replays recorded calls, interrupts the agent live, and fails the build when quality slips.

How I work

Every project runs the same loop. Real data goes in, a model decides and says how sure it is, and every number that comes out carries its receipt.

  1. Real dataGerman train delays, day-ahead power prices, speech over a phone line, real invoices.forecast-arena
  2. Model or agentSmall local decision models, large foundation models, agents that call tools.MK-SH-V
  3. Calibrated gateactask a personrefusegate-calibrated
  4. ReceiptDataset, seed and sample size next to every number, checked on every commit.voice-evals
  5. PublishedWins and failures side by side, with the code to rerun them.All 47 projects

Everything I have built

47 open repositories, grouped by what they are for. Pick a group, or open any of the 39 with a demo, a diagram and results.

Benchmarks and evaluation

Tests on real data, and the tools to run them on every commit.

  • forecast-arena Eight forecasting models on German train delays and power prices, scored against simple baselines. 19.27 MAE
  • xrechnung-bench Can a local vision model turn an invoice into a valid XRechnung 3.0.2? Checked with the official KoSIT validator.
  • voxentity-eu How exactly do speech models catch names, phone numbers and dates over a phone line? A German and French benchmark.
  • voice-evals Replays recorded calls, interrupts live agents, and fails the build when quality slips. PyPI
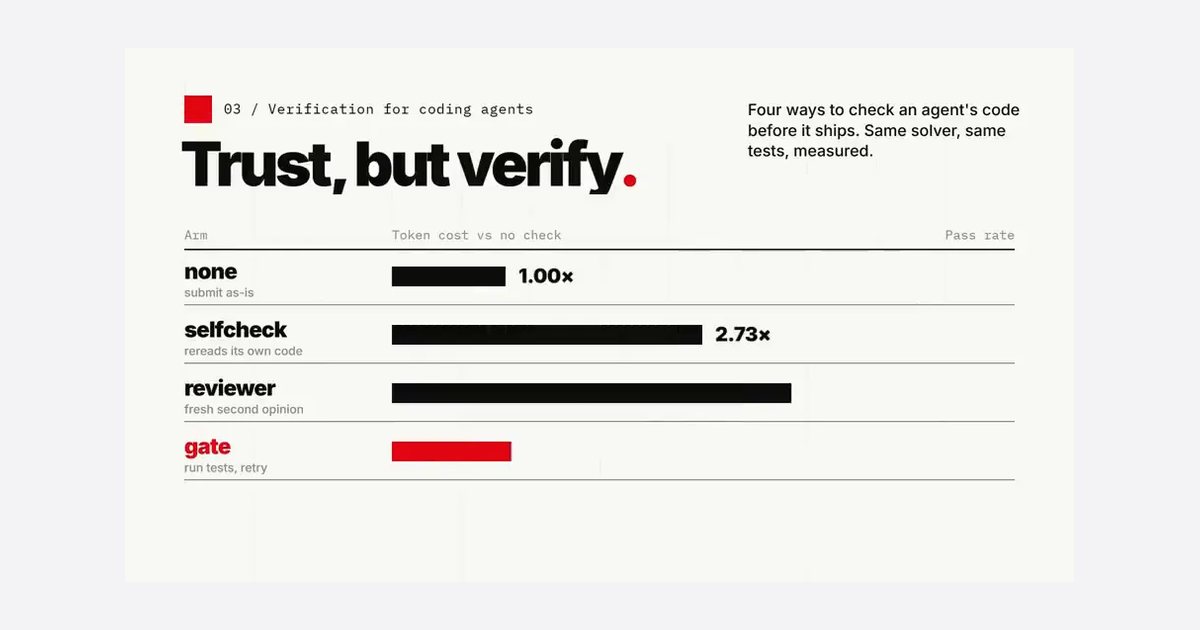
  • trust-but-verify Four ways to check a coding agent's work, priced in pass rate and tokens. +5 pts at 1.5×
  • reliagate Tells you whether an agent really improved, from repeated runs and sound statistics (pass^k, McNemar, SPRT).
  • nitelos Checks that an AI agent really did what it says it did. Python SDK. PyPI
  • vision-input-check Regression tests for vision models: does a compressed copy of the image change the answer?
  • locale-invoice-check The same invoice in English, German and Spanish. Does extraction agree on all three?
  • laya-evals Audits how far a decision model's confidence can be trusted, with reliability diagrams in CI. PyPI
  • laya-evals-gate Fails the build when accuracy drops or confidence gets less trustworthy than the committed baseline.
  • clef-evals The same confidence audit for Cloudflare's Clef decision models. PyPI

Agent reliability

When an agent may act on its own, and how to make each decision cheaper.

  • gate-calibrated Decides when an agent may write on its own and when it has to ask. Negative results included.
  • laya-warden Allows, holds or blocks every tool call an agent makes, and says why.
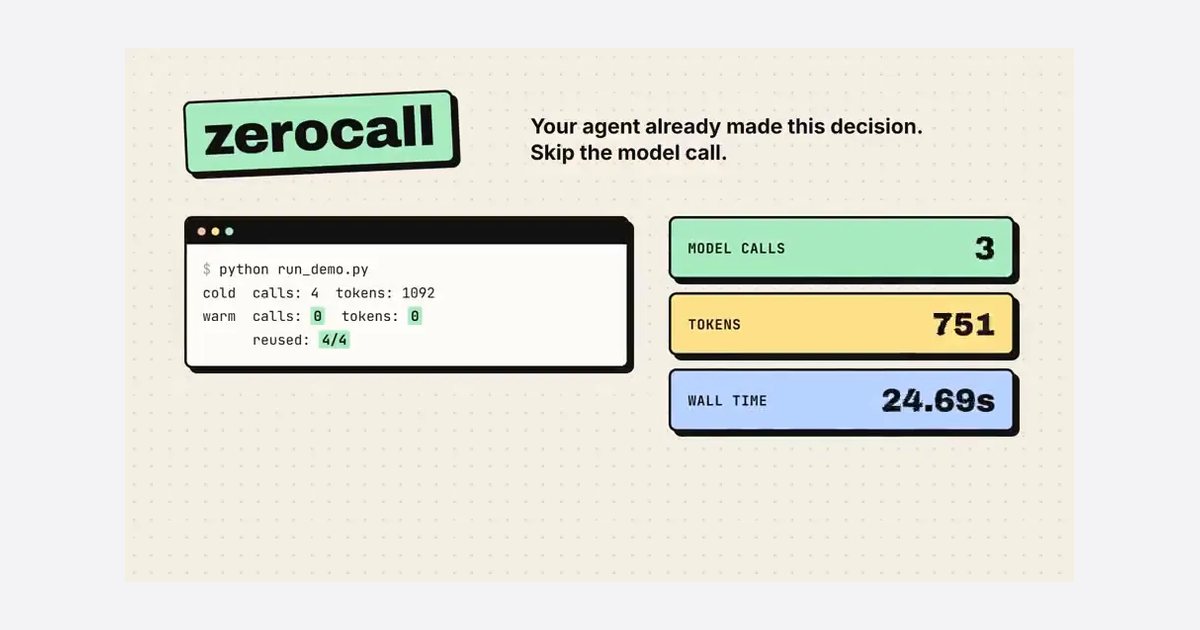
  • zerocall Skips the model call when nothing has changed since the last decision. 4 → 0 calls

Paper reproductions

Recent arXiv papers rebuilt from scratch, runnable offline, most with no dependencies.

  • decision-gate Allow, ask or block for every tool call. Counts false blocks and dangerous allows. Paper
  • routed-memory Clustered memory with routed retrieval, for a local assistant that remembers between sessions. Paper
  • agency-bench What really drives agent cost? Harness settings change the bill, not the success rate. Paper
  • compact-bench Does aggressive context compaction keep accuracy while it cuts peak context? Paper
  • wikitrace-repro Agent memory linked to its evidence, checked before every action. Paper
  • somem-repro Can agents organise their own memory? Reproduced with the standard library only. Paper
  • skillpp First open implementation of Skill++, which rewrites skill descriptions so agents pick the right one. Paper
  • drex-evals Accuracy and confidence checks for Drex decision models, offline. Paper

Decision models, routing and retrieval

Small local models that decide fast, say how sure they are, and refuse when they should.

  • MK-SH-V A 260M model that reads documents and screenshots, gives calibrated odds and refuses when unsure. 260M
  • MK-SH-1 Small local decision models that know when to abstain. Early stage.
  • laya-triage Routes tickets in any language and escalates the ones it is not sure about. 0.84
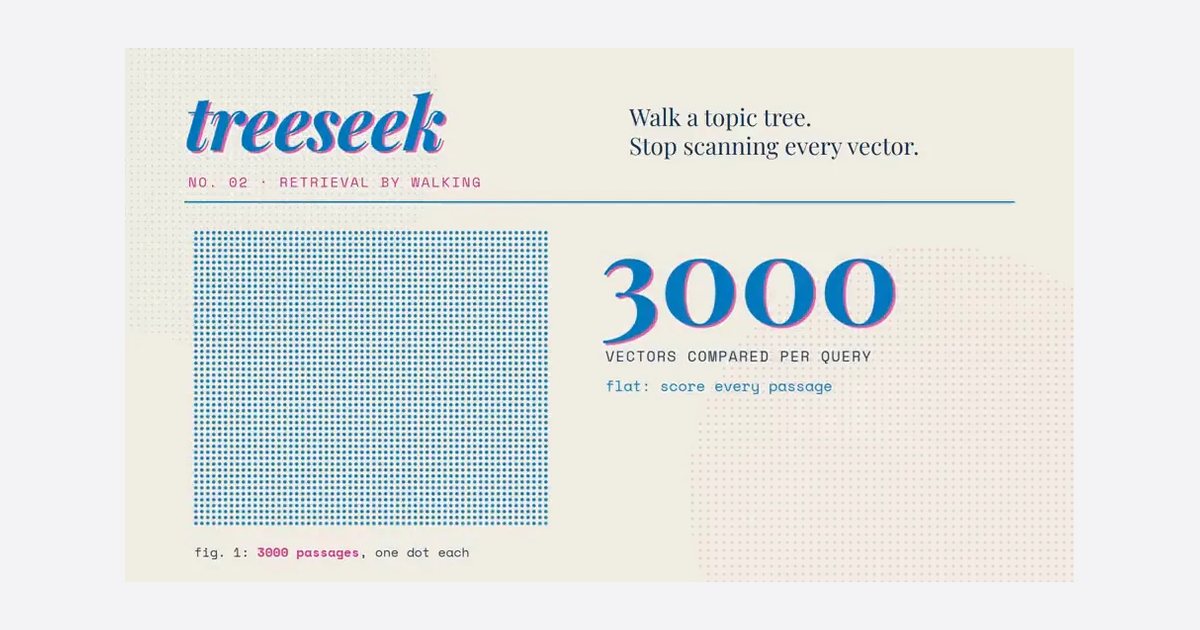
  • treeseek Search that walks a topic tree instead of comparing every vector, with the same top-1 accuracy. 74 vs 3,000
  • laya-compactor Trims retrieved context to a token budget in one local pass, without losing answer quality. −70% tokensPyPI
  • clef-compactor The same trimming with Cloudflare's Clef model. PyPI
  • laya-router Sends each prompt to a cheap or a frontier model. A drop-in, OpenAI-compatible proxy. PyPI
  • clef-router The same routing with Cloudflare's Clef decision model. PyPI
  • laya-phishield Phishing detection that explains itself: language signals plus header and link checks. PyPI

Developer tools

For people who build with coding agents and want to know what they shipped.

  • skill-issue Do your agent skills help, or only use up context? Runs the task with and without and shows the difference. npm
  • hard-mode Tests a web app under difficult conditions, such as very long text, and keeps the evidence.
  • i-didnt-write-this Vibe-coded it? Turn one feature into an interactive lesson built from your own code.

Privacy and security

For teams that answer to the DSGVO, or to their own legal department.

  • datenmaske-skills Lets coding agents find and redact German personal data, plus a DSGVO checklist for pull requests.
  • redaction-ci Fails CI when a committed PDF still contains the text it claims to have redacted.
  • piracy-watch Finds cracked copies of your software and drafts the DMCA takedown.

Products and apps

Complete applications, most of them self-hosted.

  • folio A self-hosted LaTeX editor for scientific papers. Every AI change arrives as a diff you approve. Live
  • note-lm A local research notebook. Import PDFs, videos and web pages, then ask questions and get cited answers.
  • nexary-platform An AI platform that runs inside the customer's network: chat with several providers, hybrid search, audit logs.
  • nexary Its marketing site in German, English and Spanish. Next.js 15, WCAG AA.
  • heizpro-ki A German voice agent that answers the phone for a heating company while the team is out on jobs. Demo
  • studio-command-center Runs a fitness studio: stock, machine maintenance, and staff tasks with photo proof.
  • somatriq Keeps your raw wearable data and shows how every daily score was calculated.
  • maqrivo Plans meals from your nutrition targets and real supermarket prices.
  • falschinfo-radar Finds nutrition myths in videos with reach, pins down the false claim and drafts the correction.