What it is
A deterministic, zero-dependency benchmark harness for the three context regimes of “You don’t need long context” (Belcak et al., NVIDIA, arXiv:2611.05306):
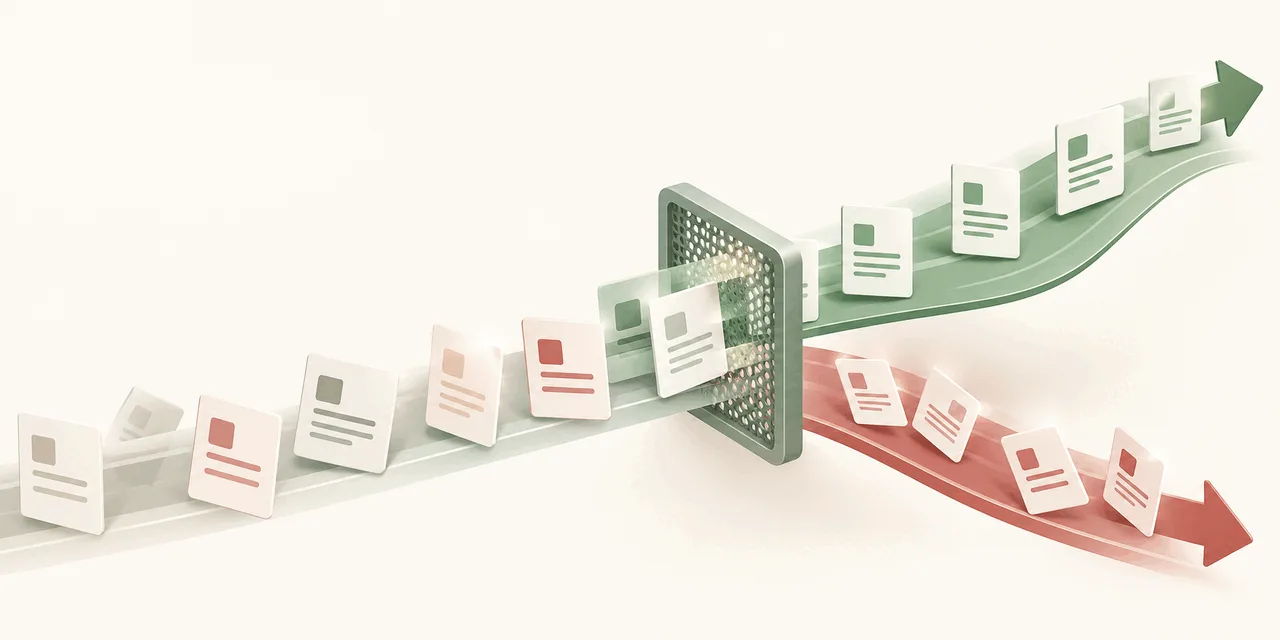
The paper’s core claim: aggressive compaction sacrifices little to no task accuracy while collapsing peak context (Opus 4.5 on SWE-bench Verified: 70.2 SAC vs 70.0 FHA with peak context 32K→8K), so long-context models may be unnecessary. compact-bench tests that mechanism on small, fully deterministic tasks, offline, with a scripted stub agent, no API needed.
Results
| Regime | Meaning |
|---|---|
| FHA: Full-History Accumulation | every action + observation stays in context (baseline) |
| EOCC: End-of-Conversation Compaction | when context crosses a token threshold, reset to task + bounded handoff state |
| SAC: Single-Action Compaction | after every action, reset to task + state (one action per context) |