What it is
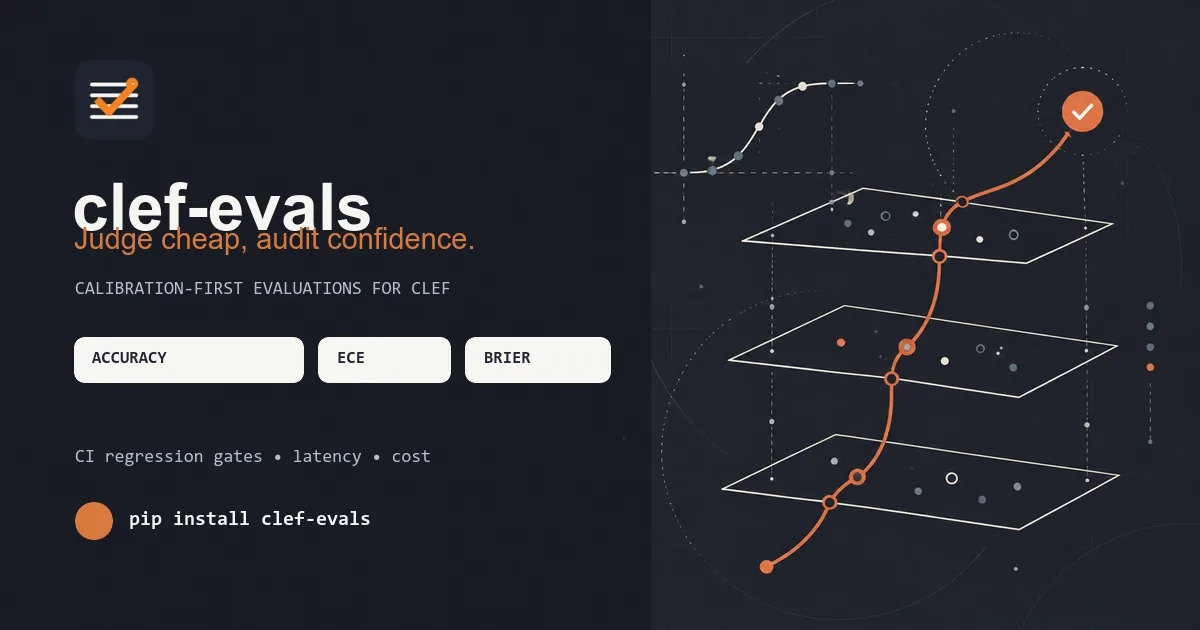
Most evaluation harnesses stop at accuracy. clef-evals also verifies whether a
model’s stated probabilities deserve to be trusted. Run typed Clef decisions
against your dataset, measure Expected Calibration Error (ECE), Brier score,
latency and cost, then make regressions fail CI before they reach users.
Results
| Evaluate | Understand | Enforce |
|---|---|---|
| Choice, binary and custom decision tasks through sync or async judges. | Accuracy, ECE, binary and multiclass Brier, latency percentiles, token use and estimated input cost. | A CLI gate and reusable GitHub Action that compare a fresh run with a committed baseline. |
Try it
pip install clef-evals
export CLEF_ACCOUNT_ID=your_account_id
export CLEF_API_TOKEN=your_api_token